
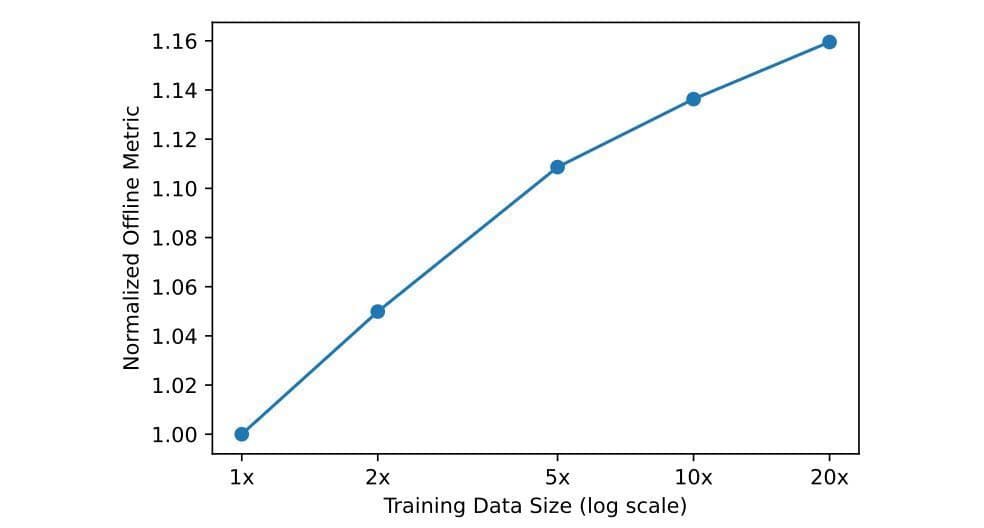
Netflix built its recommendation system on thousands of hand-crafted features, and a language model just beat it by 1.6 percent on offline ranking quality while needing roughly 40 times fewer labeled examples in the second stage of training.
That number matters more than the accuracy bump. Netflix has spent years tuning the production system GenRec was measured against.
Why the old system got expensive
The current setup leans on thousands of manually engineered features covering users, titles and interactions, according to a blog post from the Netflix tech team. All that hand-built logic makes it costly to bring on new content types like games, live formats or podcasts, and costly to push recommendations into new parts of the Netflix interface.
But you can’t just drop a stock language model into the slot either. Off-the-shelf models over-index on popular content, hallucinate titles that don’t exist in the catalog and ignore business rules.
Two rounds of training, one of them disposable
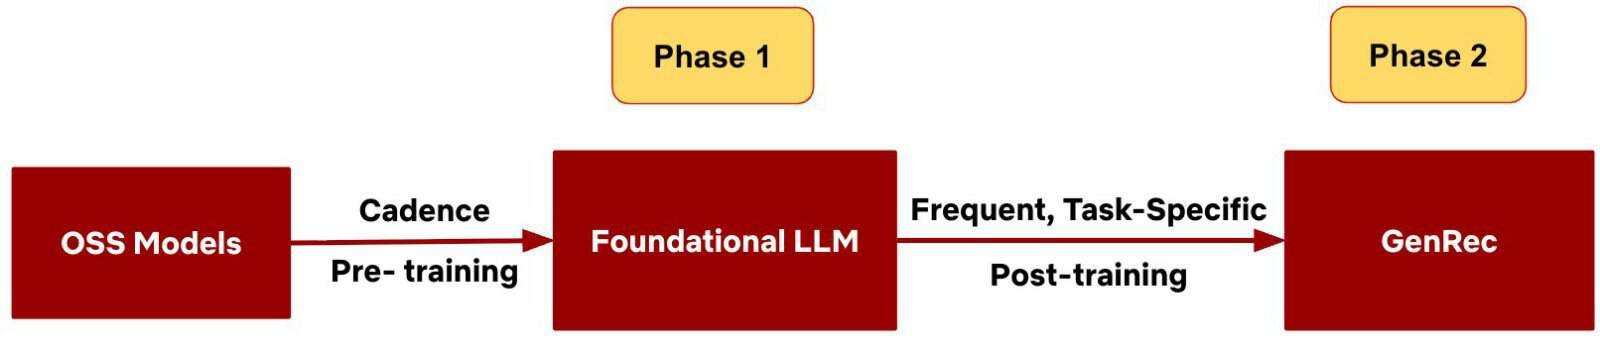
GenRec is trained in two stages. An unnamed open-weight language model gets fine-tuned on Netflix data first, so it learns the catalog and how users behave. A second round of specialized training converts that base model into a recommendation ranker.
The second stage gets refreshed far more often, because new titles keep landing and preferences keep moving.
Your viewing history, rewritten as a conversation
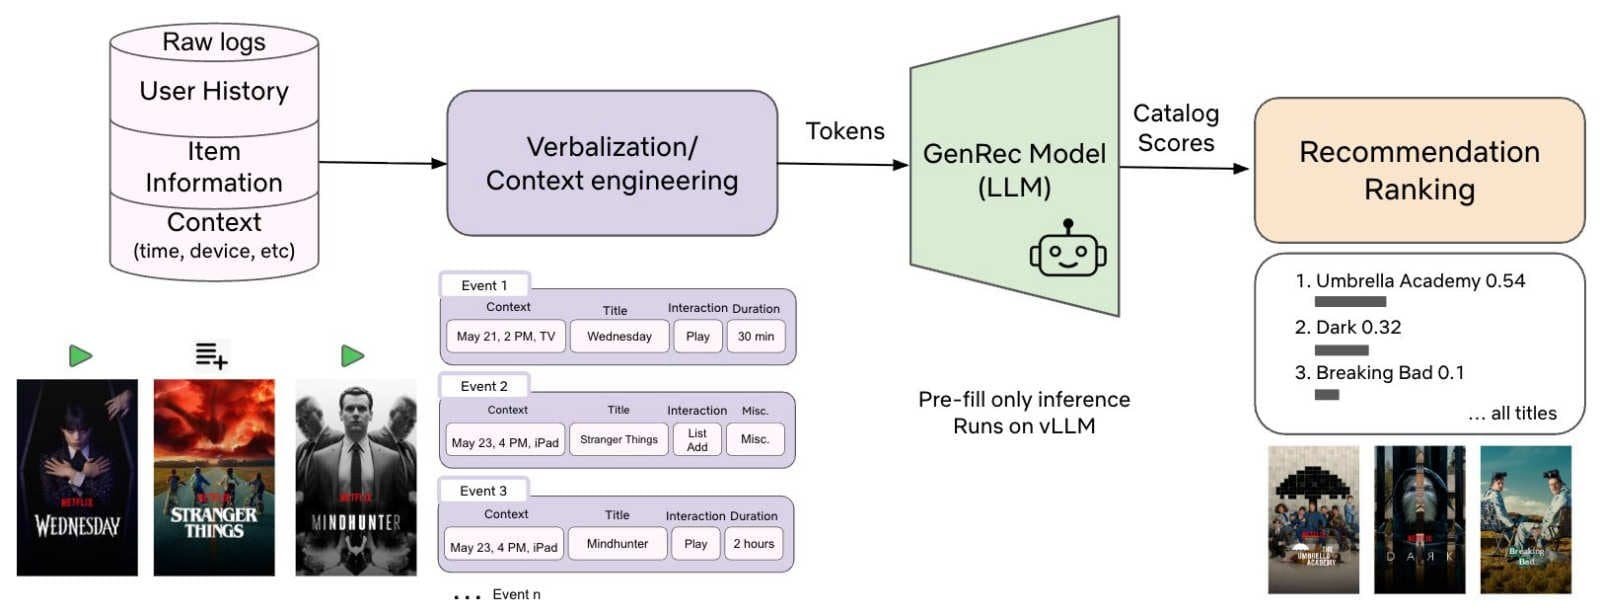
Here’s the part that breaks from convention. Rather than encoding user data as dense numerical vectors, Netflix turns it into plain text.
Plays, watch durations, thumbs up or down, list additions and drop-offs all become a kind of dialogue between you and the recommendation system. The model works out genre preferences and shifting interests on its own instead of having them spelled out through engineered features.
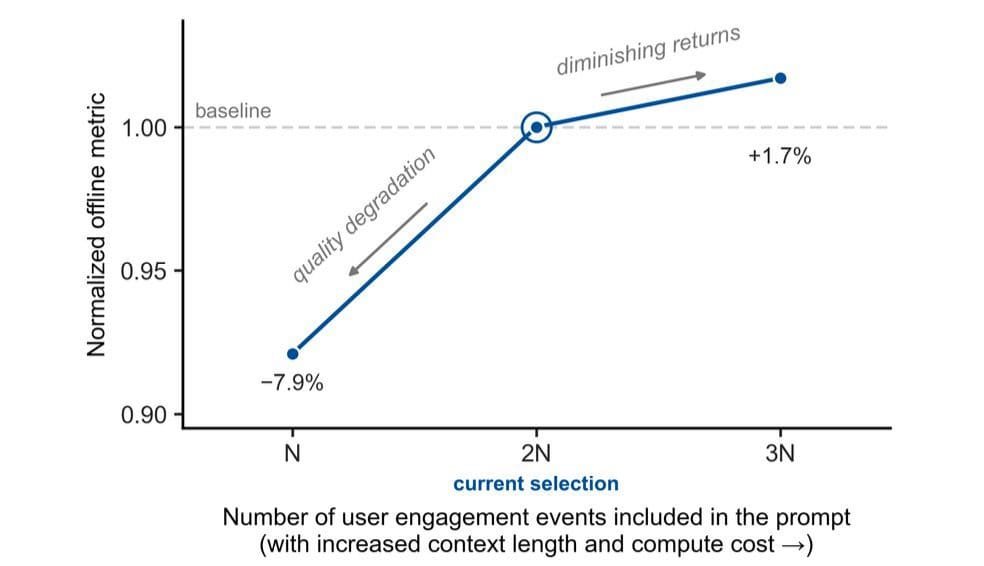
Writing out every interaction in full would overrun the context window, so Netflix cuts hard. Long watch sessions stay in full detail. Brief taps and quick scrolls get dropped, and binge sessions get condensed.
A separate component handles the hallucination problem by scoring only real catalog entries.
The efficiency trick that keeps the bill down
GenRec runs on vLLM in a mode where the model reads the input once and scores every candidate in a single pass without generating any text. No token-by-token output, no runaway inference costs.
What happened when real subscribers got it
Netflix ran a four-week A/B experiment on about ten percent of its traffic, restricted to recommendation surfaces that get pre-computed ahead of time.
A short-term metric tracking user behavior on the home screen rose by 0.115 percent. A long-term core metric improved by 0.006 percent. Those are small numbers, and Netflix says both are too large to be explained by chance.
The 1.6 percent offline gain and the 40x data reduction come with a caveat worth repeating: that comparison applies to the second training phase specifically, not to all training data.
Models go stale in two weeks
The recommendation-specific fine-tuning in Phase 2 adds another 35 to 50 percent on top of the base model’s performance. Let the base model sit for two weeks and that gap widens to roughly 80 percent, because it no longer knows about new titles or changed preferences.
Where this fits in the wider shift
Netflix positions GenRec alongside work like PLUM, GLIDE and OneRec-Think. The idea across all of them is the same: one language model covering multiple recommendation use cases instead of a custom architecture per task.
The engineering work moves too. Less time spent inventing features, more time deciding which signals belong in the model’s input and how much of each to include. Infrastructure drifts toward GPU servers and LLM tooling.
Netflix has been here before
Machine learning at Netflix stretches well past the recommendation rows. In 2020 the company described how knowledge graphs and similarity maps predict which content category a planned title fits into and what audience numbers it might reach in each country.
Google’s BERT language model handled a narrow slice of that back then, processing human-written title summaries and passing machine-readable representations to downstream models. Netflix has also started building its own models for production workflows, occasionally releasing them publicly, like the VOID framework for removing objects from video.
Don’t expect your homepage to change yet
The Netflix team calls GenRec “an early but promising step” and describes the system as a strong alternative to traditional recommendation models. A full replacement of the existing system isn’t on the table.
If you want a read on how seriously Netflix takes this, watch the training cadence rather than the accuracy charts. A system that needs its ranker retrained every couple of weeks to stay useful is a system the company has committed real infrastructure to.