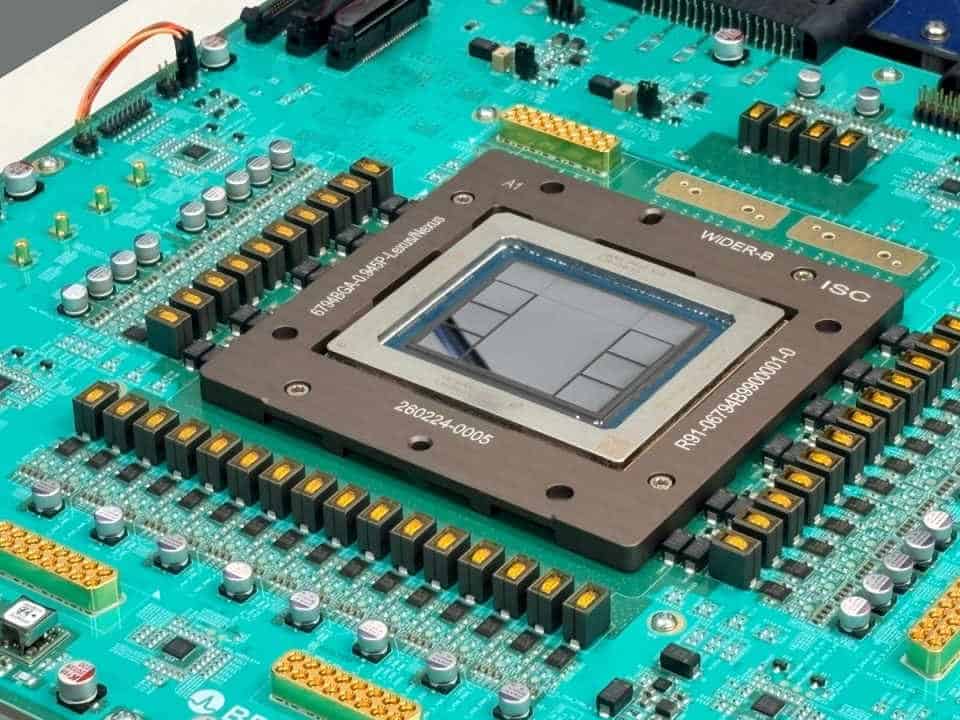

OpenAI finally put numbers behind Jalapeño, and the first ones look good. On SemiAnalysis’ InferenceX benchmark, the chip logged more tokens per user and more throughput per kilowatt than the state-of-the-art inference processors you can buy today.
The catch is the calendar. Those numbers were measured against an Nvidia Blackwell system, and Jalapeño won’t ship in any meaningful quantity until 2027.
What OpenAI showed at Hot Chips
The company laid out the details Tuesday at the Hot Chips conference, its most substantial public look at the system since the October announcement.
“The bottom line is that the results show a very, very significant performance advance over state of the art,” said Richard Ho, OpenAI’s head of hardware, in a press call. “Jalapeño can serve more AI work per unit of power, while also returning responses more quickly. It’s very efficient to serve a lot of customers, but it can also be very low latency.”
Two things at once, in other words: throughput and latency. Those usually trade against each other, which is what makes the claim worth checking when hardware actually lands in racks.
The 2027 problem
Ho said Jalapeño would deploy at the end of 2026 “in very small volumes,” with more significant deployment coming in 2027. Beating Blackwell on paper in 2026 isn’t the same as beating whatever Nvidia is selling when Jalapeño is actually running production traffic at scale.
Every custom silicon program runs into this. You benchmark against what exists, then spend two years watching the target move.
Built with Broadcom, and by OpenAI’s own models
Jalapeño was developed in close collaboration with Broadcom, and OpenAI says its own models helped with the development process. The plan is to treat it as a multigenerational platform, with AI products, models, chips and memory all developed in concert.
That full-stack framing is the actual pitch here. It’s what let OpenAI target specific phases of inference that tend to cause friction, rather than chasing a single headline throughput figure.
Where the bottlenecks actually are
The design goes after prefill and the communication phase, which OpenAI says often act as bottlenecks in inference processing. Anyone who has watched a long-context request crawl before the first token appears knows that prefill is where the wait lives.
“We designed Jalapeño to minimize data movement and communication delays,” the company said in a blog post presenting the results. “This means that model state, including the KV cache used while generating a response, can be explicitly placed and kept local while the system activates the right combination of compute, memory, and networking for each inference phase.”
Keeping the KV cache local and explicitly placed is the unglamorous part of the work, and it’s the part that determines whether the tokens-per-kilowatt number survives contact with real serving loads.
Watch the end of 2026 for those small-volume deployments. That’s the first point where the InferenceX numbers stop being a slide and start being something OpenAI has to run its own traffic on.