

Solana's Mainnet slot time is about to drop from 400 milliseconds to 350, and the per-block compute ceiling is dropping with it. That’s the part worth reading twice. Faster blocks, but not more compute per second.
The 350ms target takes effect in epoch 1020. The feature itself activated at the start of epoch 1019, at slot 440,208,000, but a one-epoch delay written into SIMD-0525 means the network keeps its existing parameters until the next epoch rolls over. So blocks get a shorter target production interval without a larger compute allowance per second.
The test clusters are already well past this
Testnet is running an effective 200ms target. Devnet sits at 300ms and has activated its 250ms gate without making it effective yet.
Solana's Aug. 6 changelog listed only the 350ms step on those two clusters. Two weeks of movement since then tells you how fast the later stages have advanced.
And a caveat that gets skipped in most of the excitement: SIMD-0525 is still a draft. Feature activation means a specific cluster change is moving through the network. It doesn’t mean the full 200ms design is an accepted final standard. These are also target timings, which aren’t the same thing as observed block production, confirmation latency or economic finality.
The math that keeps the ceiling flat
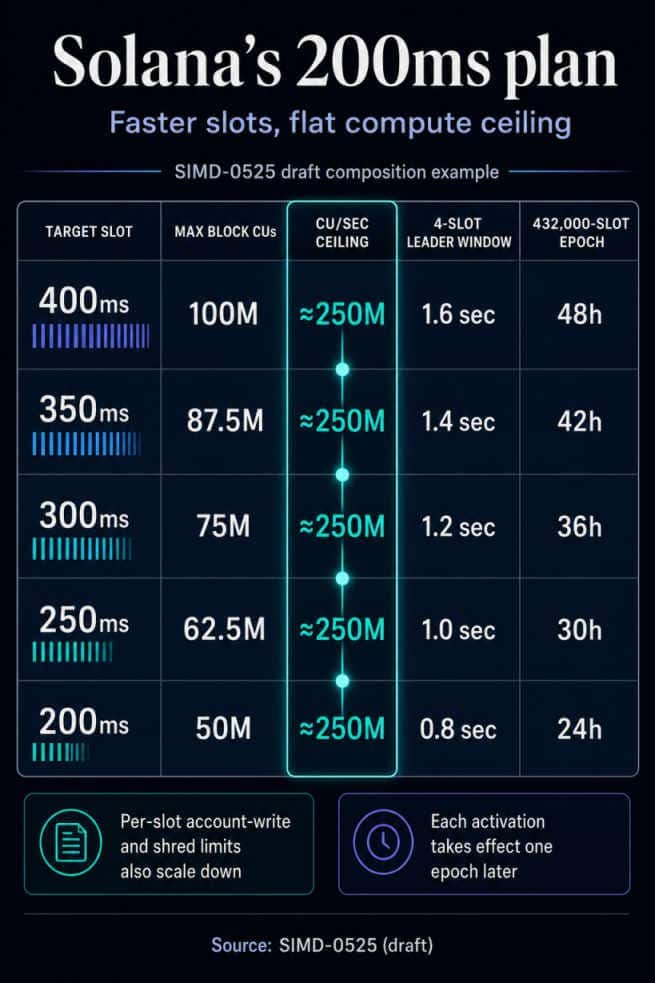
Solana's July 30 changelog reported Mainnet had already activated a maximum block limit of 100 million compute units. SIMD-0525 lays out how that 400ms maximum composes with each slot-time stage: 87.5 million CUs at 350ms, 75 million at 300ms, 62.5 million at 250ms and 50 million at 200ms.
Run the arithmetic on any of those rows and you land at roughly 250 million CUs of theoretical maximum block budget per second. Halve the target slot time and the example’s block-compute ceiling barely moves.
That ceiling isn’t a throughput forecast. Actual use depends on workload and network conditions, and the 100 million figure is a composition example for maximum block CUs, not a universal baseline for every limit.
Compute isn’t the only budget getting trimmed
The proposal also reduces per-slot account-write, vote, data-allocation, data-shred, coding-shred and partitioned-reward budgets. The point is to create more frequent scheduling opportunities without quietly doubling what validators may be asked to process each second.
A limit describes the most work a block may contain. Not how much work every block will contain. Shorter target slots can change when a transaction gets an inclusion opportunity even while the theoretical per-second compute allowance stays flat.
Leaders get a much smaller window
Each leader still gets four consecutive slots. At 400ms per slot, that’s a nominal 1.6-second leader window. At 200ms, it’s 0.8 seconds.
Half the time under one leader’s control. Less time to receive the previous block, replay it, build on it and land votes before the network moves on.
Handoff and propagation margins tighten accordingly. Vote and gossip events happen more often in the same wall-clock interval, and block packing and Turbine have to enforce smaller, slot-aware budgets after each delayed transition. Every stage is a live coordination test as much as a latency win.
Your epoch clock is about to lie to you
SIMD-0525 keeps each epoch at 432,000 slots. The slot count doesn’t change, but its wall-clock meaning does: nominal epoch duration falls from roughly 48 hours at 400ms to 24 hours at 200ms.
This is where it bites software outside the validator. Some SDK constants and off-chain assumptions are still tied to 400ms, so an app that estimates elapsed time by multiplying a slot count by 400ms can disagree with the cluster once a faster stage goes effective.
RPC clients, explorers and other off-chain services that use slot distance to estimate freshness or elapsed time are in the same position. The proposal’s longer-term direction is for software to pull effective timing parameters from the cluster rather than treat a compile-time constant as permanent.
The economic version of the same bug
Alpenglow’s Validator Admission Ticket shows what the mismatch looks like in money. The scaling in SIMD-0525 applies only if the dependent Alpenglow VAT mechanism is active, in which case the proposed charge falls from 1.6 SOL per epoch at 400ms to 0.8 SOL per epoch at 200ms, preserving an approximately 0.8 SOL daily target.
The available evidence doesn’t establish that VAT collection is active on any cluster. Worth holding onto before anyone quotes those numbers as live validator economics.
For Mainnet, what’s actually happening is 350ms in epoch 1020. Not a jump to 200ms. Solana is rotating scheduling opportunities sooner while holding resource ceilings roughly constant, and the open question at every stage is whether validators and the infrastructure around them can hold their coordination margins as the window keeps shrinking. Watch the leader handoffs, not the headline number.

[…] Faster slots mean faster confirmations. They don’t raise the network's overall throughput. […]